GT / 2026Engineering workspace 001

I BUILD
SOFTWARE
SYSTEMS.

Software engineering Data engineering AI systems

Full-stack products, data platforms, distributed systems and AI workflows engineered end-to-end.

System / request path6 layers

Client

Browser

React and Next.js on the edge — server components where rendering belongs on the server.

A working model. Select a layer to inspect its boundary.

Scroll to explore
01 — Work

Selected Work

Systems I've designed, engineered and shipped.

01Full-Stack Product · Distributed Business Logic

SplitSmart

Shared-expense settlement with an auditable ledger

A shared-expense platform where the hard part is not the arithmetic but the invariants: members join and leave over time, four different split modes have to agree, and every mutation has to stay auditable.

Year
2026
Status
Building
Stack
Next.js · React · TypeScript · Prisma · PostgreSQL

Engineering challenge

Keeping settlement correct while group membership changes over time, and keeping every correction traceable rather than silently overwritten.

Approach

Modelled membership as a timeline rather than a flag, so an expense is always apportioned against the members active at its date. Balances are reduced with a greedy debt-simplification pass, and every mutation is written to an append-only audit log with JSON old/new value diffs.

Full-Stack Product · Distributed Business Logic / flow5 stages

Client

Users

Authenticated group members acting on shared state.

Engineering detail

  • 10-model PostgreSQL schema covering groups, members, expenses, splits and audit history
  • Active/inactive member timeline invariant, so historical expenses are never reapportioned
  • Four expense split modes — equal, exact, percentage and share-weighted
  • Greedy debt simplification that collapses circular balances into the fewest transfers
02AI Research Infrastructure

InvestIQ

A reviewed research pipeline, not a single model call

An equity-research system built as an explicit state graph. Research fans out into parallel analysis, a thesis is drafted, and a reviewer node can send it back — a bounded critique loop rather than one prompt and a hope.

Year
2026
Status
Building
Stack
Next.js · TypeScript · LangGraph.js · Google Gemini · Tavily

Engineering challenge

Getting reviewable output out of a language model, and giving the user visibility into a multi-stage process that takes time to run.

Approach

Modelled the workflow as a LangGraph.js state graph with a reviewer node and a conditional rejection edge, so a weak thesis is sent back for revision inside a bounded loop. Node transitions stream to the client over Server-Sent Events, making a slow pipeline legible while it runs.

AI Research Infrastructure / flow6 stages

Retrieval

Research

Tavily search plus Yahoo Finance data, so the graph reasons over live sources.

Engineering detail

  • 5-node LangGraph.js state graph with explicit transitions between stages
  • Live research data retrieved through Tavily rather than model recall
  • Yahoo Finance integration supplying quantitative market context
  • Parallel analysis fan-out, so independent angles are evaluated concurrently
03Security · Real-Time Systems

ChatPulse

A messaging server that cannot read its own traffic

End-to-end encrypted messaging where the private key never leaves the browser. The server relays ciphertext and wrapped session keys, and holds nothing it could decrypt.

Year
2026
Status
Building
Stack
Node.js · Express · Socket.io · MongoDB · WebCrypto

Engineering challenge

Delivering real-time messaging while making it structurally impossible for the server — or anyone who compromises it — to read message contents.

Approach

Key generation happens in the browser with WebCrypto and the private key is persisted only to IndexedDB. Each message is encrypted with a fresh AES-256-GCM session key, which is then RSA-wrapped for the recipient. The server relays ciphertext and wrapped keys, and MongoDB TTL indexes expire ephemeral records without intervention.

Security · Real-Time Systems / flow6 stages

Client

Sender

Generates the RSA-OAEP key pair in-browser; the private key stays in IndexedDB.

Engineering detail

  • RSA-OAEP key pair generated in the browser via WebCrypto
  • Private key stored only in IndexedDB — it is never transmitted
  • Per-message AES-256-GCM encryption with a fresh session key
  • RSA key wrapping, so the session key travels encrypted to the recipient
04Data Engineering · Machine Learning

Flight Delay Data Pipeline

Six stages from raw rows to a served model

A six-stage pipeline that generates, cleans, models and serves flight-delay predictions. Every stage is idempotent, so a rerun converges instead of duplicating.

Year
2026
Status
Live
Stack
Python · Pandas · PostgreSQL · Scikit-Learn · XGBoost

Engineering challenge

Making a multi-stage pipeline safe to rerun, so that evaluation reflects the data and features actually intended rather than accumulated duplicates.

Approach

Split the pipeline into six discrete stages with a 4-table Postgres model separating raw, cleaned and feature data. Loads are idempotent, so any stage can be re-executed without corrupting downstream state. The trained XGBoost model is served through a Flask REST API with a Streamlit dashboard for exploration.

Measured

  • ROC-AUC 0.710 on the synthetic evaluation set.

Built on a synthetic 100,000-row dataset whose delay labels come from a known generator formula, so the reported score describes model fit on generated data — not real-world operational performance.

Data Engineering · Machine Learning / flow6 stages

Source

Generate

Produces the 100,000-row synthetic dataset from a known formula.

Engineering detail

  • 6-stage pipeline: generate → clean → feature engineer → load → train → evaluate
  • 100,000-row dataset
  • 4-table PostgreSQL model separating raw, cleaned and feature data
  • Idempotent reruns — re-executing a stage converges rather than duplicating rows
05Streaming Data Engineering

Real-Time Retail Data Pipeline

Streaming ingestion with a replayable staging layer

Retail transactions streamed through Kafka into Spark Structured Streaming, staged on S3 so batches can be replayed, then loaded into Redshift under Airflow orchestration.

Year
2026
Status
Live
Stack
Python · Apache Kafka · Spark Structured Streaming · Airflow · Amazon S3

Engineering challenge

Handling continuous transaction volume while keeping a path back to the source data when a transformation turns out to be wrong.

Approach

Kafka retains the event log, Spark Structured Streaming processes it in micro-batches, and every processed batch lands on S3 before Redshift. That staging layer makes reprocessing possible without re-ingesting. Airflow orchestrates the downstream steps with task-level retries.

Streaming Data Engineering / flow5 stages

Ingestion

Kafka

Durable event log for retail transactions, with retention that permits replay.

Engineering detail

  • Kafka → Spark Structured Streaming → S3 → Redshift
  • Micro-batch processing through Spark Structured Streaming
  • Replayable S3 staging layer — batches can be reprocessed after a logic fix
  • Airflow orchestration across the load and transform steps
06Distributed Systems

Distributed Web Crawler

Coordinating five workers over shared Redis state

A multi-worker crawler where the interesting problem is coordination: a shared frontier, a shared visited set, and politeness rules that must hold across every worker at once.

Year
2026
Status
Building
Stack
Python · Redis · MongoDB · BeautifulSoup · Docker Compose

Engineering challenge

Keeping five concurrent workers from duplicating fetches or violating per-domain politeness, when the constraint has to hold globally rather than per worker.

Approach

Moved queue state, deduplication and rate limiting into Redis so all workers share one view. The frontier is a sorted set giving priority ordering, the visited set prevents duplicate fetches, and the 1-second per-domain gap is enforced centrally. The whole topology runs under Docker Compose.

Distributed Systems / flow6 stages

Redis sorted set

Frontier

Priority-ordered URL queue shared by every worker.

Engineering detail

  • 5 worker threads pulling from one shared frontier
  • Redis sorted-set frontier providing priority ordering across workers
  • Shared visited-set coordination, so no URL is fetched twice
  • robots.txt compliance checked before fetching

Also built

  • End-to-End Flight Data Warehouse

    2026

    Snowflake warehouse integrating flight operations and passenger data, transformed with dbt and orchestrated by Airflow over a star schema.

    Snowflake · dbt · Airflow · SQL

  • Retail ETL Pipeline

    2026

    Automated batch ETL moving retail data from source extracts through transformation into an analytical store.

    Python · Pandas · SQL

  • Big Data Processing with PySpark

    2026

    Distributed processing of large datasets using PySpark, covering partitioning and aggregation across a cluster.

    PySpark · Python

  • Streaming Transaction Pipeline

    2026

    Live transaction ingestion and processing, an earlier iteration of the retail streaming architecture.

    Kafka · Python

  • E-Commerce Data Warehouse Design

    2026

    Dimensional model for e-commerce analytics — fact and dimension design following Kimball methodology.

    SQL · Dimensional Modelling

02 — Systems

Data Systems

From raw events to reliable analytical systems.

Platform topology8 stages

Origin

Sources

Transactional systems, events and third-party APIs.

Batch Processing
Scheduled transformation over bounded datasets.
Stream Processing
Continuous micro-batch handling of event data.
ETL / ELT
Extract and load patterns chosen per warehouse target.
Data Modeling
Star schemas, fact and dimension design.
Orchestration
DAG scheduling with task-level retries.
Data Quality
Validation and anomaly rules before commit.
Analytics
Query-ready models serving reporting layers.
03 — Method

How I Build

  1. 01

    Systems First

    Understand the architecture before writing the implementation.

  2. 02

    Reliability by Design

    Retries, validation, idempotency, observability and failure recovery should be intentional.

  3. 03

    Security Is a Feature

    Protect data at the architecture level rather than adding security as an afterthought.

  4. 04

    Ship, Measure, Improve

    Build real systems, evaluate their behaviour and iterate based on evidence.

04 — Stack

Technology

Every tool below has shipped in something on this page. Select one to see where.

Languages

Frontend

Backend

Data

Data Engineering

AI / ML

Infrastructure

The number beside a technology is how many of the builds on this page use it.

05 — About

Engineer. Builder. Problem Solver.

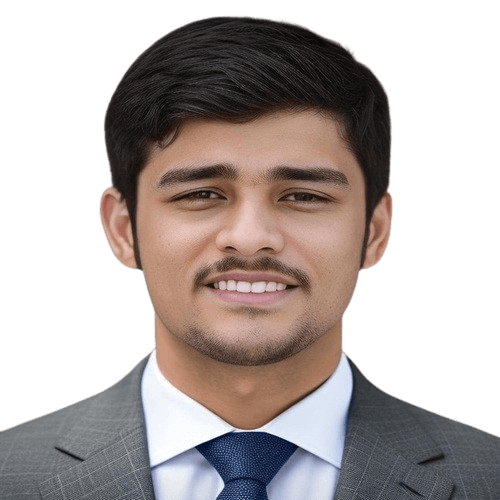
I'm a final-year Computer Science engineering student at Lovely Professional University, graduating in 2027. Most of what I know about software came from building things that had to actually work — an expense splitter that has to survive concurrent edits, a crawler that has to survive its own workers dying, a pipeline that has to survive a broker restart.

My interest sits one level below the interface. I like the part of the problem where you decide what the boundaries are: what runs synchronously and what gets queued, where state lives, what happens on the second attempt. A feature is finished when it behaves correctly on the unhappy path, not when it renders.

The work splits across three areas that keep converging — full-stack product engineering, data platforms that move events into queryable models, and AI systems built as orchestrated graphs rather than single prompts. The builds listed above are where each of those was worked out in practice.

Degree
B.Tech, Computer Science & Engineering
Institution
Lovely Professional University
Graduating
2027
CGPA
7.26
Gaurav Tiwari

Gaurav Tiwari

Certifications

  • OracleOracle Cloud Infrastructure 2025 Certified Data Science Professional
  • NPTELCloud ComputingVerify
  • CodeQuestCodeQuest DSA Summer Bootcamp100+ problems across arrays, graphs and dynamic programming
06 — Experience

Timeline

The record so far, by year.

202611 systems

  1. SplitSmartFull-Stack Product · Distributed Business Logic

    Shared-expense settlement with an auditable ledger

  2. InvestIQAI Research Infrastructure

    A reviewed research pipeline, not a single model call

  3. ChatPulseSecurity · Real-Time Systems

    A messaging server that cannot read its own traffic

  4. Flight Delay Data PipelineData Engineering · Machine Learning

    Six stages from raw rows to a served model

  5. Real-Time Retail Data PipelineStreaming Data Engineering

    Streaming ingestion with a replayable staging layer

  6. Distributed Web CrawlerDistributed Systems

    Coordinating five workers over shared Redis state

  7. End-to-End Flight Data WarehouseSnowflake · dbt · Airflow · SQL

    Snowflake warehouse integrating flight operations and passenger data, transformed with dbt and orchestrated by Airflow over a star schema.

  8. Retail ETL PipelinePython · Pandas · SQL

    Automated batch ETL moving retail data from source extracts through transformation into an analytical store.

  9. Big Data Processing with PySparkPySpark · Python

    Distributed processing of large datasets using PySpark, covering partitioning and aggregation across a cluster.

  10. Streaming Transaction PipelineKafka · Python

    Live transaction ingestion and processing, an earlier iteration of the retail streaming architecture.

  11. E-Commerce Data Warehouse DesignSQL · Dimensional Modelling

    Dimensional model for e-commerce analytics — fact and dimension design following Kimball methodology.

2027Expected

B.Tech, Computer Science & Engineering

Lovely Professional University · CGPA 7.26

07 — Public

Building in Public

Every system on this page has its source open.

@gauravtiwarrii
Public repositories
Stars received
Primary languages

Recently pushed

Want the full technical profile?

Two versions, depending on the role you're hiring for.

08 — Contact

LET'S BUILD
SOMETHING
USEFUL.

Open to software engineering, data engineering and AI systems opportunities.